Cloud and platform
OpenTelemetry: observability without vendor lock-in
How to connect traces, metrics and logs around operational questions instead of decorative dashboards.
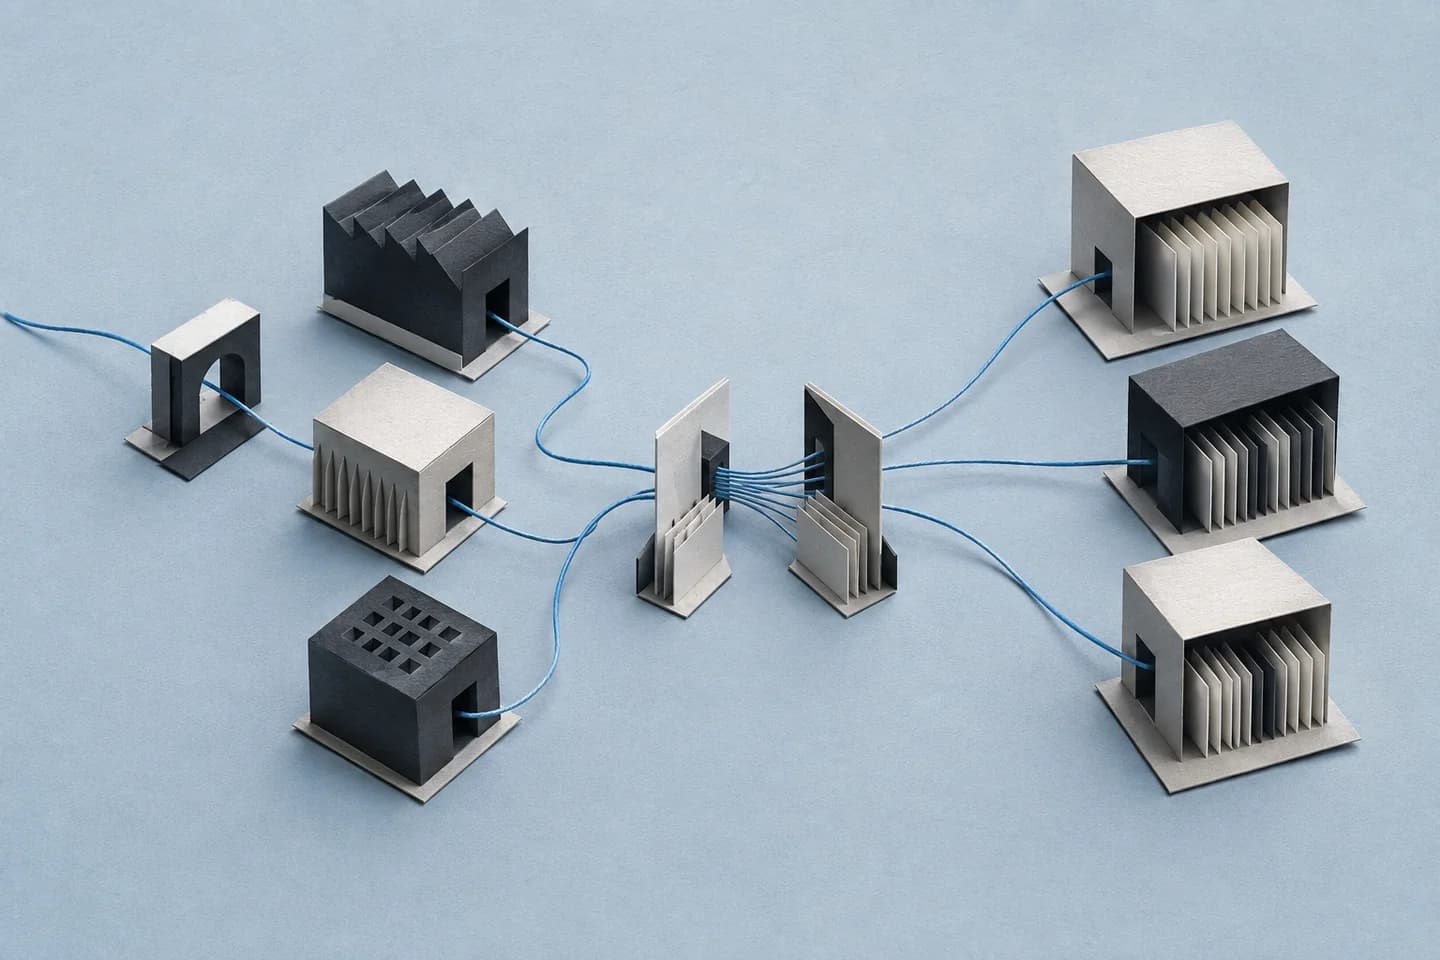
The central idea
A useful trace preserves context across services and answers an operational question at a sustainable collection cost.
Observability means explaining internal state from system outputs. OpenTelemetry provides vendor-neutral instrumentation, collection and export for traces, metrics and logs, but it is not the storage backend.
Adoption works best around critical journeys. Context propagation connects a request to dependencies, errors and latency without reconstructing the story manually.
The path of an observable signal
01
Application
Traces, metrics and logs
02
Collector
Process, filter and sample
03
Backend
Store and query
04
Response
SLO, alert and investigation
The Collector decouples applications from destinations and can enrich, filter, sample and export signals while protecting sensitive data.
Instrumenting everything without a model raises cost and noise. Naming conventions, cardinality limits, retention and service objectives should come before more dashboards.
Start with operational questions
Write the questions before adding instrumentation: which payments complete, where latency accumulates, which dependency explains an error and which version introduced the regression. Those questions define attributes, events and metrics. Instrumenting first often creates expensive data nobody knows how to query.
Propagate context end to end
The trace identifier should cross HTTP, messaging and asynchronous jobs. Spans need stable names and controlled-cardinality attributes. Unique identifiers, emails and full payloads are poor metric dimensions and can expose sensitive information.
Use the Collector as an operating boundary
A per-node deployment or central gateway can enrich signals, remove secrets, apply sampling and route by environment. Topology depends on volume and failure tolerance. The Collector also needs its own metrics: queues, drops, export latency and memory pressure.
Control cost and noise
Sampling should preserve errors, slow operations and high-value journeys instead of using only a uniform percentage. Retention and resolution differ by signal. A useful alert maps to a service objective and includes enough context to begin investigation without opening five dashboards.
Teaching case
Payment succeeded, but confirmation never arrived
A checkout API accepts an order, publishes a message and delegates confirmation to a worker. The API responds quickly while the customer keeps waiting. The useful journey ends when confirmation reaches the customer.
Instrument reception, publication, processing and completion. Carry context in message metadata, using parent relationships or span links as appropriate, especially for batches. Correlated error logs explain an execution; queue-age metrics reveal whether the problem is widespread.
Head sampling cannot know the final outcome. Tail sampling can consider duration and errors but requires buffering and collecting spans. A Collector cannot recover traces already discarded upstream. Set the sampling policy together with collection capacity and privacy limits.
Choices and their tradeoffs
| Situation | Choice | Tradeoff |
|---|---|---|
| Measure failure frequency | Use bounded aggregate metrics. | They lack individual execution detail. |
| Find a slow dependency | Trace across service boundaries. | Sampling leaves some journeys unrecorded. |
| Explain a specific failure | Correlate structured logs. | Exclude secrets and full payloads. |
Scroll the table to compare all three columns.
Put it into practice
Rehearse an end-to-end investigation
- Delay a worker in a test environment.
- Navigate from degradation to a trace and dependency.
- Interrupt export and observe Collector queues, drops and recovery.
What to verify: You can explain where the journey stalled and detect gaps in telemetry itself.
Neutrality with purpose
OpenTelemetry reduces instrumentation lock-in, but it does not remove product decisions. Success is measured by how quickly a team can explain an incident and verify an improvement, not by how many signals it stores.
Continue reading
Cloud and platform
The internal platform now serves teams and agents
Golden paths, self-service and policies for organizations where people and agents consume the same platform.
Cloud and platform
FinOps on Azure: from monthly cost to product value
An operating cycle to allocate spend, detect waste and make technical decisions with business context.