Data
PostgreSQL 18 and hybrid search: text and vectors together
When to combine lexical retrieval, pgvector and reranking without creating an unnecessary data platform.
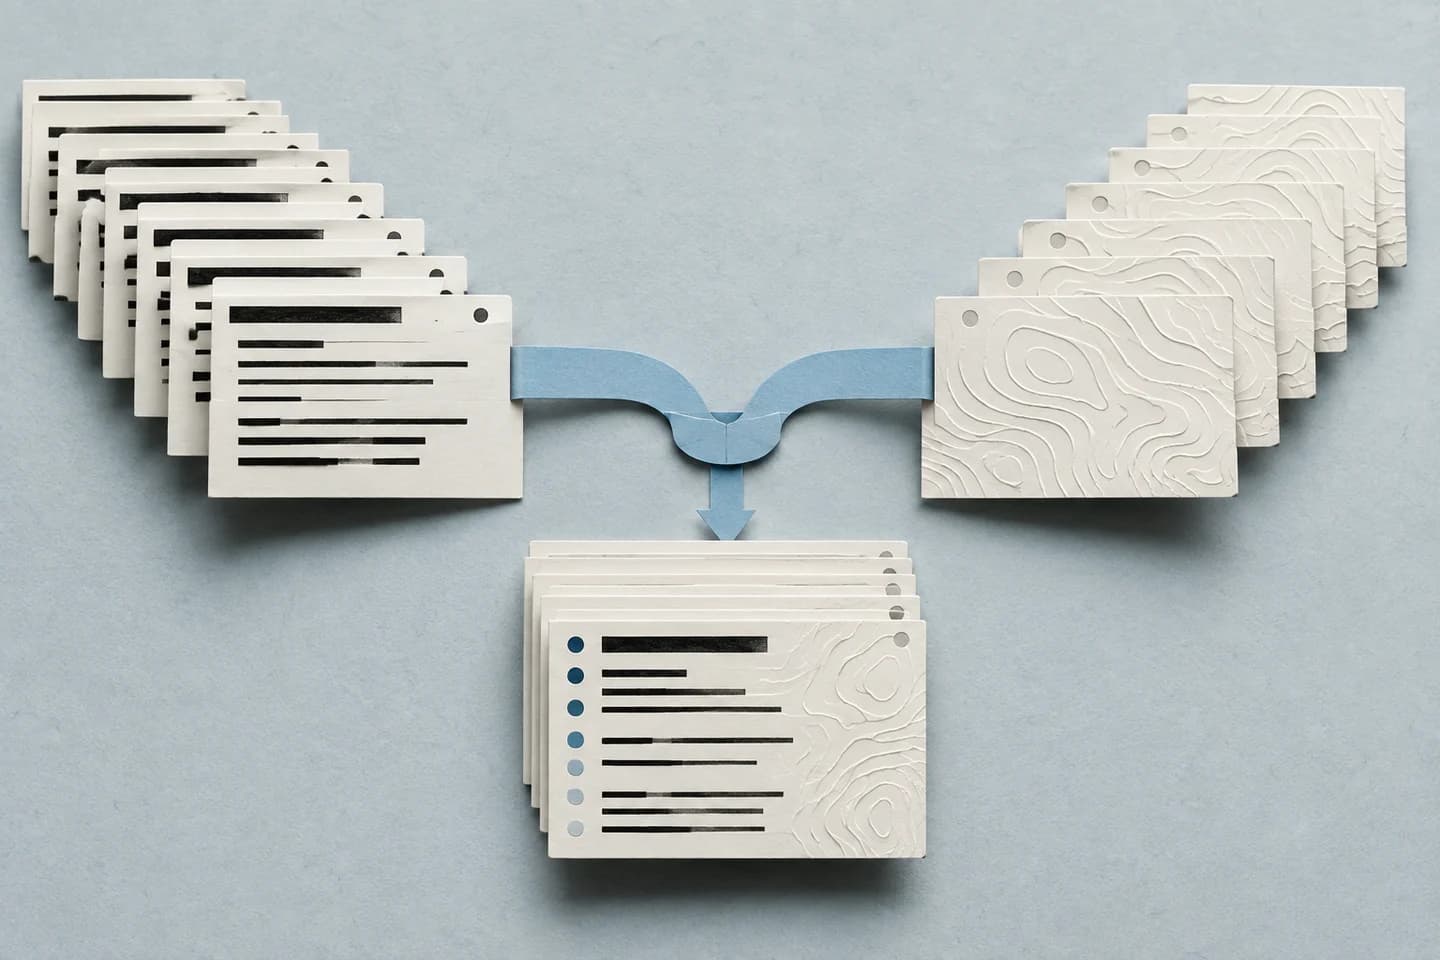
The central idea
Retrieve by wording and meaning, apply permissions to both paths and measure relevance before adding ranking complexity.
Semantic search finds conceptual similarity while lexical search preserves exact terms, codes and names. Hybrid retrieval combines candidates from both before optional reranking.
pgvector supports exact search plus HNSW and IVFFlat. HNSW often offers a stronger speed-recall tradeoff at the cost of memory and build time, and it must be measured with real filters.
Hybrid retrieval pipeline
01
Text
Terms and codes within authorized content
02
Vectors
Conceptual similarity within authorized content
03
RRF fusion
Combine ranks
04
Final ranking
Results ordered by relevance
PostgreSQL 18 improves I/O, indexing and observability around these workloads, but quality still depends on embeddings, partitioning, updates and relevance metrics.
Keeping text, permissions, metadata and vectors in PostgreSQL often reduces synchronization and operational surface until scale proves a specialist engine is needed.
Separate retrieval and ranking
The first stage seeks broad coverage and returns candidates. The second combines signals and orders them. This separation reveals whether the problem lives in embeddings, lexical queries, filters or reranking. It also avoids asking an expensive model to inspect documents that never belonged in the candidate set.
Choose indexes with real filters
HNSW and IVFFlat behave differently under memory, updates and tenant filters. Benchmarks need real distributions, languages and permissions. A fast index that loses relevant documents after filtering misses the product goal even when its isolated latency looks excellent.
Fuse without calibrating incompatible scores
Reciprocal Rank Fusion combines positions without assuming text scores and vector distance share a scale. Weights can vary by query type. Exact codes favor lexical search; conceptual questions often benefit more from semantic signals.
Measure quality, latency and operations
Use a query set with relevance judgments and metrics such as recall, MRR or nDCG beside p95 and cost. Monitor index growth, vacuum, embedding updates and permission consistency. Search is a product capability, not one isolated query.
Teaching case
Find a policy by code or by meaning
In support search, “ERR-1042” needs an exact match while “I cannot log in after changing phones” needs conceptual proximity. Build representative queries for both, including unanswerable questions and restricted documents.
RRF adds 1 / (k + rank) for each list containing a document. With an illustrative k of 60, positions 1 and 8 yield about 0.03110; positions 3 and 2 yield 0.03200. The second document wins through stronger joint placement. This k illustrates arithmetic rather than guaranteeing relevance.
Deduplicate documents and retain candidate origin for debugging. Apply access filters in both retrieval paths before exposing content to a reranker or model. Selective filters can reduce approximate-search candidates; compare against exact search and measure recall and latency.
Choices and their tradeoffs
| Situation | Choice | Tradeoff |
|---|---|---|
| Exact codes and names | Ensure lexical retrieval. | Identifiers may need special normalization. |
| Paraphrases | Add semantic candidates. | Similarity does not prove an answer exists. |
| Incompatible score scales | Evaluate rank fusion. | RRF discards original score magnitude. |
Scroll the table to compare all three columns.
Put it into practice
Evaluate before changing engines
- Review expected results and permissions for a query set.
- Compare lexical, vector and hybrid with the same result limit.
- Inspect relevance failures and selective filters.
What to verify: Representative queries improve while access isolation and latency stay within budget.
A database before a platform
PostgreSQL can solve hybrid search with less synchronization and consistent permissions. A specialist engine should be introduced after measuring real limits, not before proving that added complexity buys a relevant improvement.
Continue reading
AI and agents
MCP agents: useful by design, safe by control
How to expose tools to an agent without turning every integration into an implicit permission.
Cloud and platform
The internal platform now serves teams and agents
Golden paths, self-service and policies for organizations where people and agents consume the same platform.